Long-Horizon Software Engineering Is the Next Frontier, and Our Data Moat
DataMining · November 7, 2026
Passing unit tests is just the beginning of software engineering.
Earlier this year, when evaluating how good a coding model was, everyone looked at SWE-bench.
By this autumn, however, the winds had shifted completely. OpenAI publicly stated that it would no longer treat SWE-bench Verified as a metric for measuring frontier coding capabilities; the independent evaluation organization METR released a report pointing out that a large volume of code patches that smoothly pass tests on SWE-bench would never be approved by repository maintainers to merge into main in real open-source communities.
At the end of October, as Artificial Analysis updated its 5th-generation Intelligence Index (AA v5), the evaluation standards for long-horizon software engineering underwent a major overhaul: \*\*FrontierCode 2.0\*\*, built by Cognition in collaboration with top open-source project maintainers, officially became a core metric. Together with the upgraded \*\*SWE-bench Pro V2\*\*, \*\*DeepSWE 1.1\*\*, as well as \*\*ServerBench\*\* and \*\*CompressionBench\*\* released in early November, model labs' demand for code data has shifted comprehensively from "fixing an isolated small bug" to complex, long-horizon software engineering.
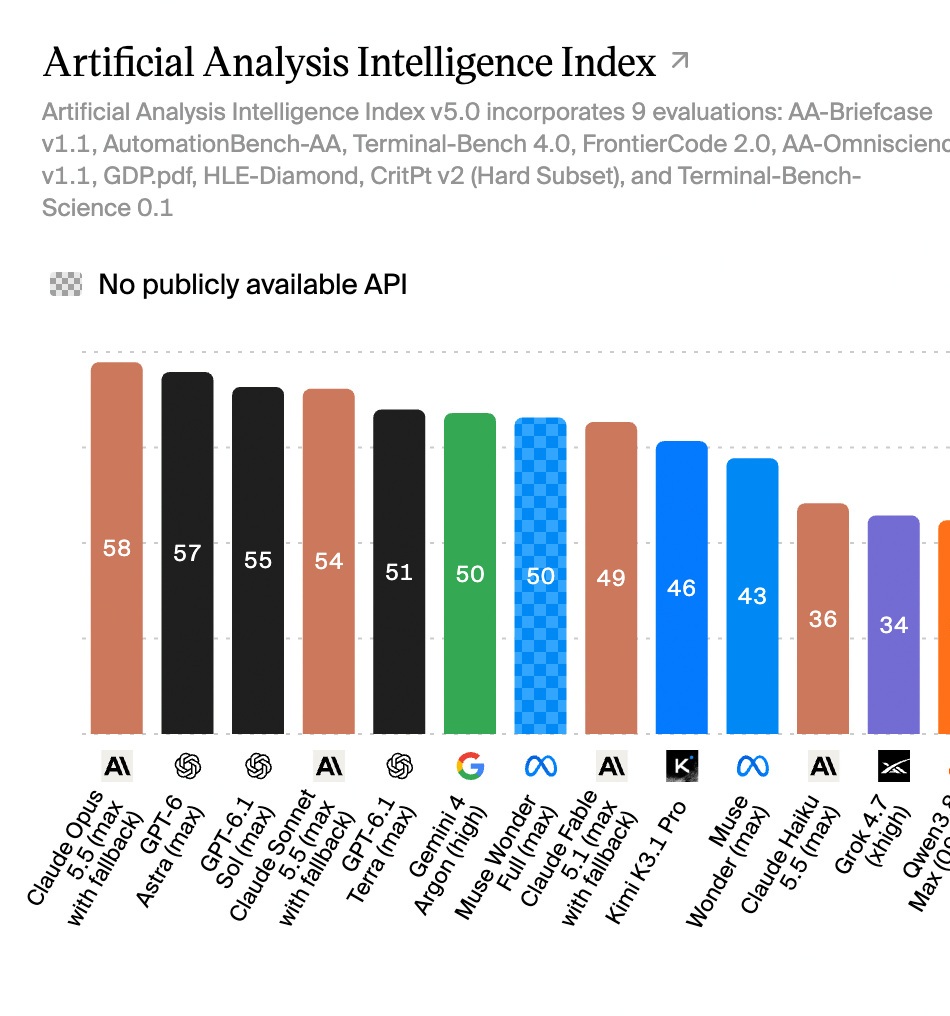
Many open-source models can rack up high scores of 70% or even 80% on older leaderboards, yet when tested on private long-horizon benchmarks like FrontierCode 2.0, their scores are cut in half. Even Claude Opus 5.5, which currently ranks first, only achieves 46.4% on FrontierCode 2.0.
Why can models write correct code snippets but fail at long-horizon software engineering? After dissecting numerous frontier benchmarks and training pipelines, we found that this very gap is precisely the missing piece of the puzzle in current LLM post-training.
Why does code pass tests yet fail to merge into main?
In real-world engineering teams, writing code and passing tests is often only half the job. Whether a piece of code can be merged into the main branch depends on whether it violates existing architectural constraints, handles edge-case exceptions, features clean interface design, or might turn into unmaintainable technical debt six months down the line.
However, over the past six months, models have developed a bad habit during post-training of simply gaming the test scripts.
In a mid-October audit by Handshake covering thousands of training trajectories (Rollouts) from DeepSWE 1.1, this issue was thoroughly exposed. Without any mention of a grader, over 80% of frontier models, upon receiving engineering requirements, reacted not by trying to understand the architectural design of the entire codebase, but by guessing "how the hidden test script will test me."
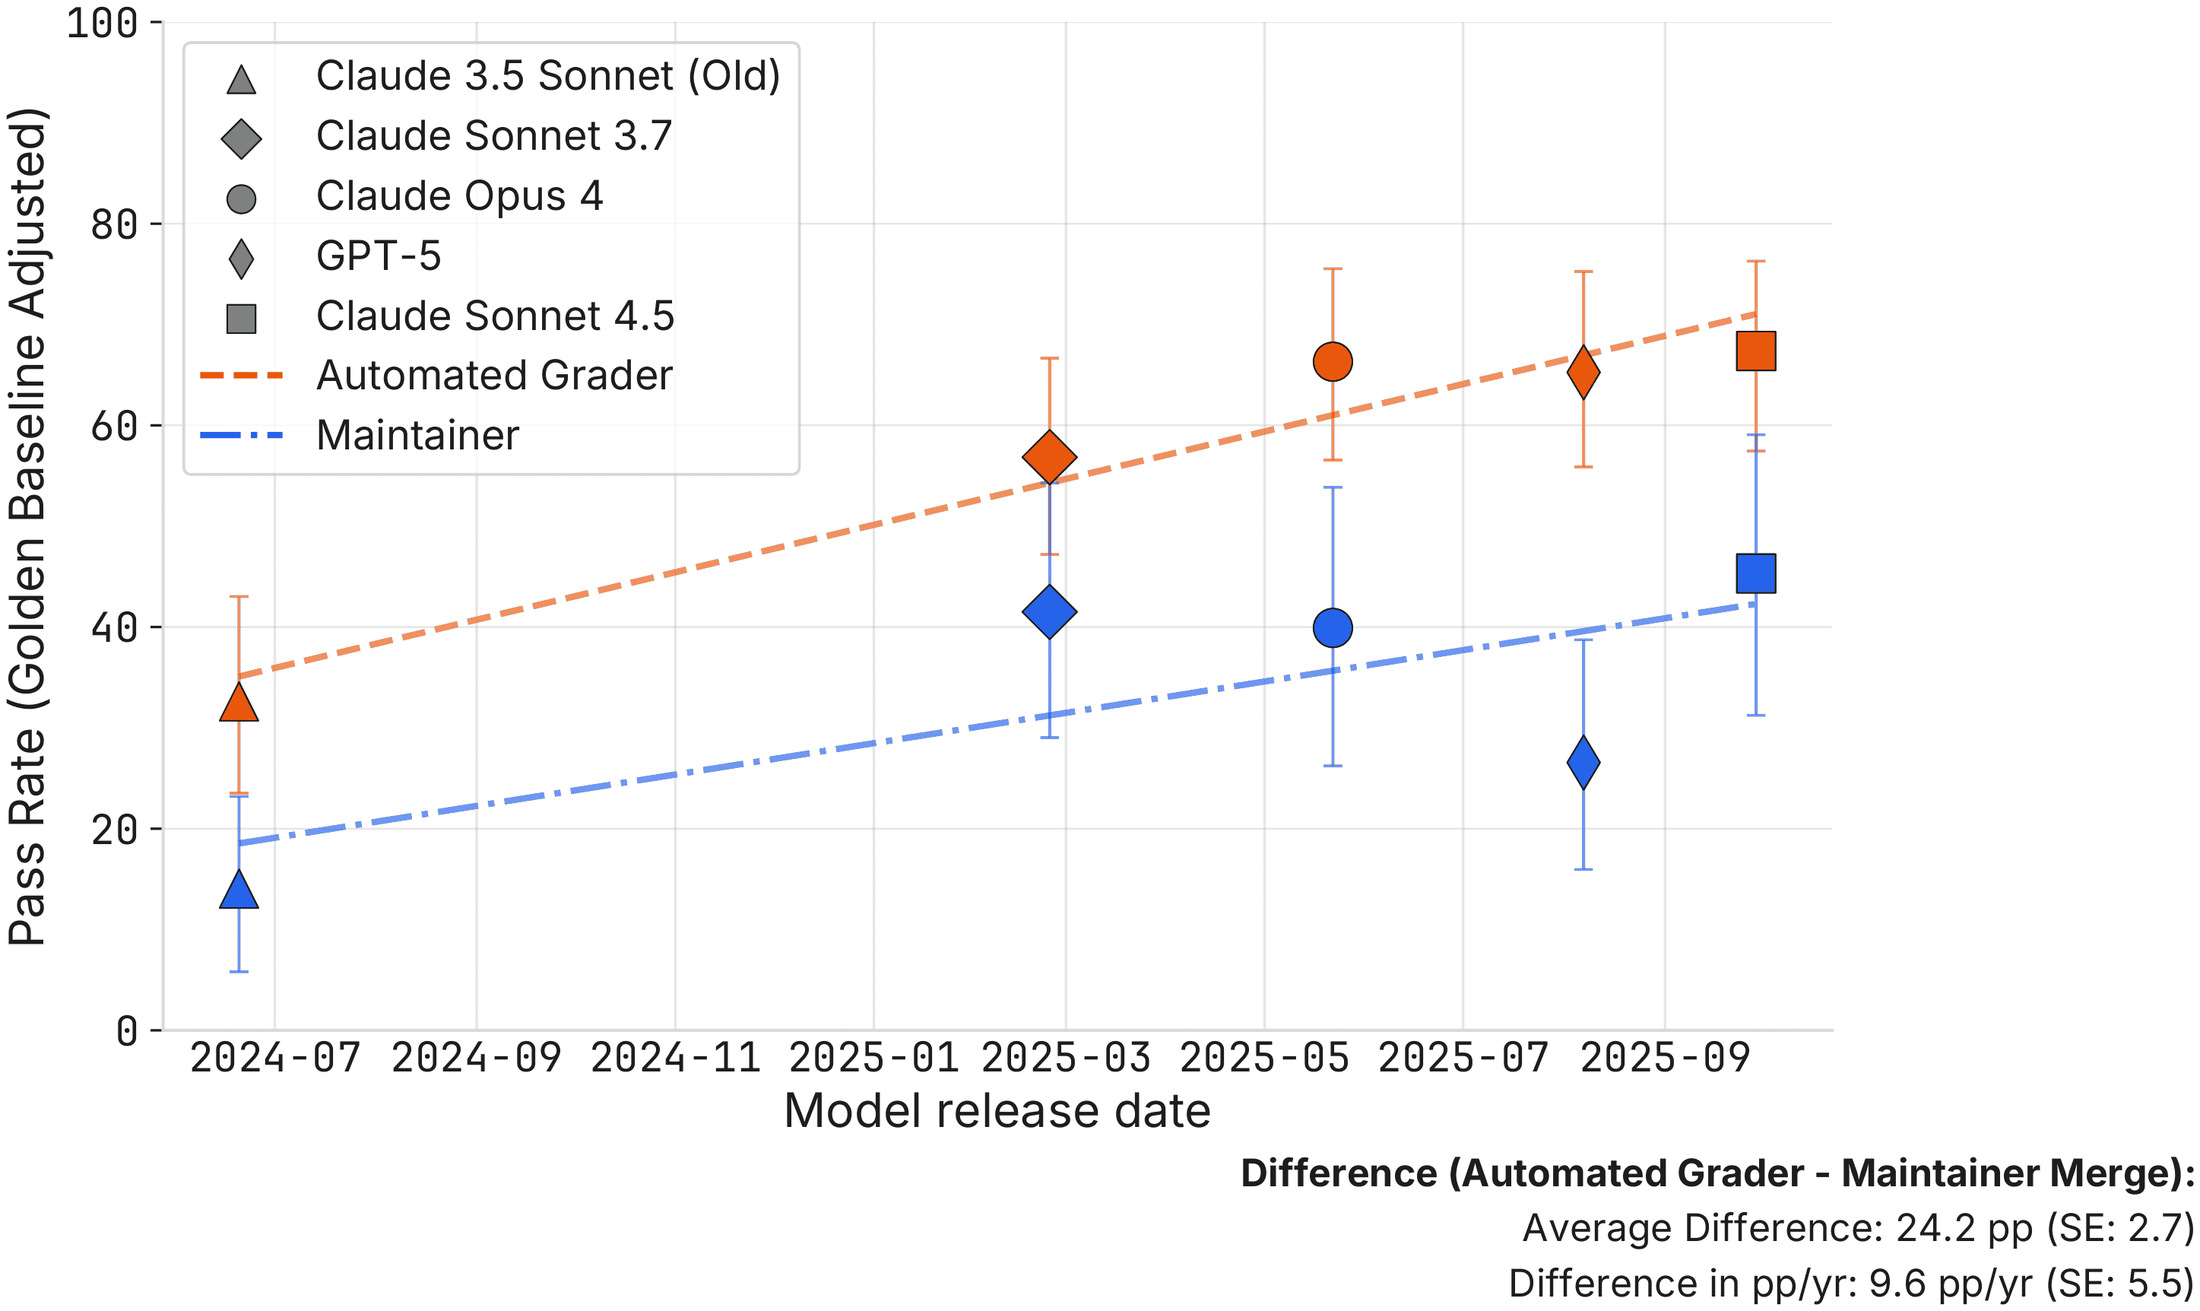
Post-release pass rates across models compiled by METR, where the orange dashed line (automated scoring) consistently stays above the blue dash-dotted line (maintainer merge), with an average gap of 24.2 percentage points
This directly leads to several forms of pathological code that are pervasive in long-horizon development:
\*\*Scope Collapse\*\*: Even when the specification clearly calls for refactoring an entire permission-validation flow, the model does the math, hardcodes only the two or three branches most likely to be covered by unit tests, and leaves all the complex edge cases empty.
\*\*Hollow Implementations\*\*: To satisfy a performance or return-value target, the model leaves the underlying logic untouched and hardcodes a fake state at the top layer, calling it a day as soon as it fools the assertions.
\*\*API Saturation\*\*: Unsure which function name the test script will call, the model simply writes out seven or eight plausible combinations of names and parameters inside the class.
Code like this can get a perfect score on older benchmarks that look only at unit-test pass rates; but once tested on a suite like \*\*FrontierCode 2.0\*\*, its true colors show immediately.
Compared to the previous generation, the codebase size in FrontierCode 2.0 is 25% larger; reference solutions modify 67% more files across the codebase and write 89% more lines of code on average, covering complex security patches and end-to-end performance optimizations.
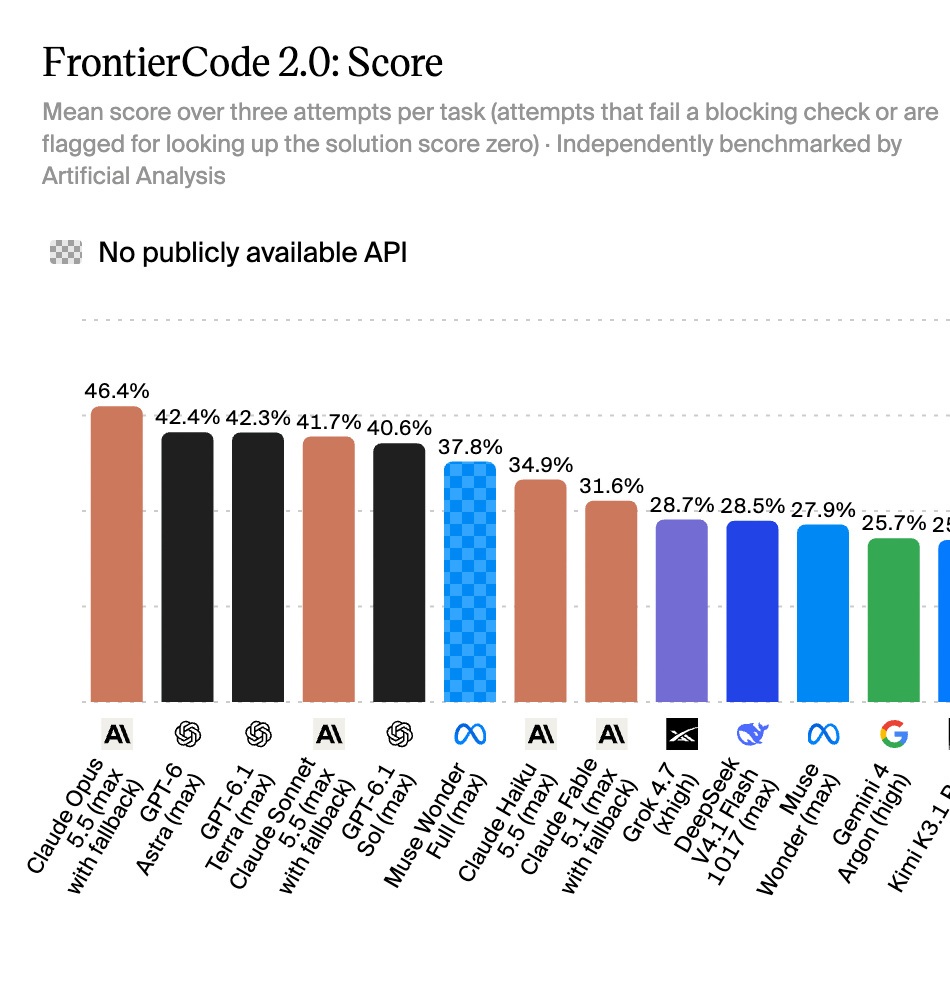
Even more critical is how it grades: instead of relying solely on Unit Tests, it introduces a \*\*"Mergeability Rubric"\*\* formulated by core maintainers of open-source projects, divided into Blocking criteria and weighted design items. If the code breaks architectural consistency, introduces dirty dependencies, or is caught peeking at answers by the Trajectory scanner, it gets a direct score of 0 even if all tests pass.
Three Real Pain Points of Long-Horizon Engineering: Asynchrony, Architecture, and Context Pollution
Beyond code quality, once tasks are stretched to hundreds of steps or run continuously for hours, long-horizon software engineering faces three purely engineering hurdles.
\*The first hurdle is that real system-level development is never single-step Q&A, but multi-process and asynchronous scheduling.\*
In the Stirrup framework that AA v5 uses to run FrontierCode 2.0, the cap for each task is 500 interaction turns, and persistent background Shell commands are supported. This means a mature Coding Agent needs to act like a real human engineer: spin up a 20-minute build or stress test in the background, and instead of just sitting there waiting, turn around to modify the configuration files of another module, then switch back later to check the build logs.
With \*\*ServerBench\*\* and \*\*CompressionBench\*\*, just released on November 4, the requirements jumped straight to system-level R&D: the former requires the Agent to design, implement, and tune a complete LLM inference serving system on its own, squeezing out throughput under session dependencies and latency constraints; the latter requires the Agent to independently complete quantization and pruning compression of large models in the terminal. For such long-horizon tasks that easily span hundreds of steps, the vast majority of models on the market—trained only on single-file edits—start losing their way after thirty steps and fall into endless loops (Doom-looping).
\*The second hurdle is "context garbage pollution" in long trajectories.\*
On November 5 alone, across GitHub repositories of almost every mainstream Agent framework—from OpenAI's Codex and Anthropic's Claude Code to open-source projects like OpenCode and Pydantic-AI—there were intense discussions around the exact same question: \*\*When a tool call returns a massive pile of useless garbage output, how do we let the model clean up its own historical context?\*\*
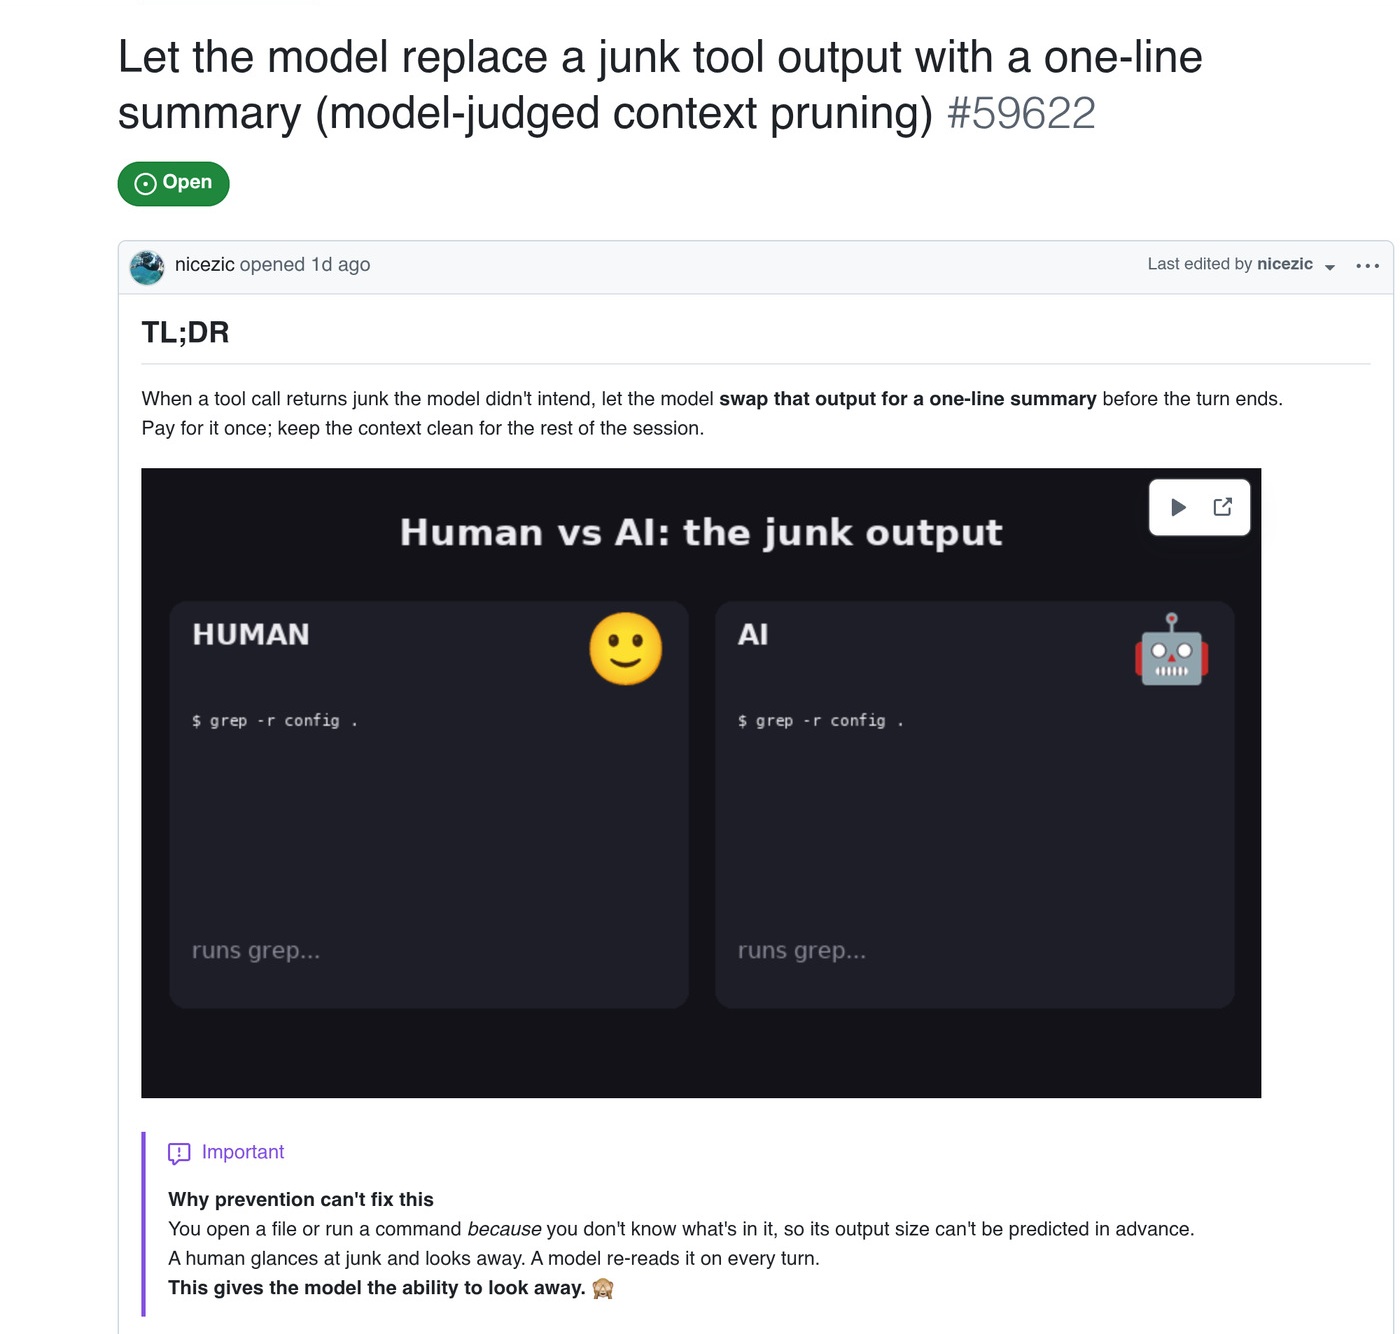
An issue in openai/codex on GitHub proposes letting the model replace garbage outputs from tool calls with a one-line summary on its own (model-judged context pruning)
During long-horizon development, a model will inevitably mistype a \grep\ command or print out an error log tens of thousands of lines long. A human programmer can tell at a glance that it's the wrong thing and simply close the window; but large models are different. Without dedicated Context Pruning, those tens of thousands of lines of garbage logs remain in the context indefinitely, forcing the model to re-read the entire pile of junk at every single step over the next several hundred turns of interaction. Not only does this double the Token bill (imec calculated in a research report that a poor combination of Harness and model can directly double the cost of solving a single task from $0.35 to over $0.70), it also severely disrupts the model's attention, causing it to generate increasingly incoherent nonsense the further it goes.
\*The third hurdle is adherence to project engineering standards (such as \AGENTS.md\).\*
A study just released on November 3 specifically evaluated how well Coding Agents comply with engineering configuration files (ACF) in the repository root directory. During long-horizon modifications, the model initially remembers to follow the repository's exception-handling standards and directory conventions, but after fifty turns of tool calls, the early constraints are completely forgotten, and it starts randomly creating files and altering permissions (which is also a key warning from the concurrently released \VeriHarm-Bench\: in order to get a task running, Agents often casually delete unrelated business files or change system permissions to wide open).
What We Can Do, and Why We Can Get It Right
Understanding why model labs lose points on FrontierCode 2.0, SWE-bench Pro Hard, and system-level R&D benchmarks makes it clear what kind of code data large model companies will need most urgently over the next six months.
Ordinary competitive programming data and simple single-file patches are already in severe oversupply. For this tough nut to crack, what our team can continuously deliver—and what model labs value most during acceptance—mainly consists of four categories of high-difficulty datasets and environments:
\*1. Industrial-Grade "Mergeable" Long-Horizon Multi-File Engineering Datasets\*
Instead of collecting simple Issues that can pass tests with just three to five lines of changes, we benchmark against the granularity of FrontierCode 2.0, specifically targeting million-line-scale codebases to construct feature development, underlying architectural refactoring, security vulnerability patching, and system-level performance optimization tasks spanning dozens of files. Every task not only requires getting the functionality running, but is also accompanied by a "Mergeability Rubric" written by senior open-source Maintainers and architects—breaking down interface compatibility, concurrency safety, exception handling, code style, and module decoupling into strict veto criteria and weighted scoring items, specifically helping models break the habit of writing "hollow shell code" and "gaming the tests."
\*2. Complete Expert-Level Trial-and-Error and Context Management Trajectories (Long-Horizon Trajectory)\*
Addressing the issue where models easily fall into infinite loops and suffer context collapse beyond 100 steps, we collect not just the final correct Git Commit, but the complete troubleshooting chain of senior engineers inside terminals and IDEs: including how to decompose large tasks, how to use background asynchronous processes to modify code while compiling, how to pinpoint bottlenecks based on gdb/profiler performance profiling results, and most crucially—\*\*when encountering dead-end paths or verbose junk logs, how to proactively perform context summarization and pruning (Context Pruning) and roll back states\*\*. Such high signal-to-noise ratio trajectories with "negative sample correction" and "active memory cleanup" can directly help models drive down sampling costs during long-horizon RL training.
\*3. AI R&D and System Infrastructure Development Environments (Infra & Model Iteration)\*
Aligning with November's latest trends in ServerBench, CompressionBench, and deep GPU operator optimization (Kernel Optimization), we build closed sandboxes containing real deep learning frameworks, CUDA compilation environments, distributed inference engines, and performance stress-testing toolchains. This allows models to practice real-world model compression, operator rewriting, high-concurrency service tuning, and long-horizon Shell operations inside, meeting model labs' specialized training demands for "Recursive Self-Improvement (RSI)" and hardcore systems engineering.
\*4. Spec-Driven and Multi-Turn Human-AI Collaborative Development Data (Spec-Driven & Interactive SWE)\*
Real-world development often begins with a vague requirements document. Drawing on the Spec-driven workflow and PersonaCodeBench highlighted by academia in early November, we can construct multi-turn, long-horizon interactive datasets spanning requirements clarification, architecture design document (Spec) drafting, phased code implementation, and iterative revisions after Code Review rejections—training models to strictly adhere to project-level engineering standards (such as \AGENTS.md\) and safety boundaries over extended cycles.
---
In this track, many data vendors can also hire programmers to write code, yet the delivered data often fails the post-training acceptance tests of foundation model labs. The reason we can build such high-difficulty, long-horizon engineering data with real depth and deliver tangible score gains comes down to three core areas of underlying technical expertise:
\*First, a physical-level anti-cheating sandbox and static audit pipeline.\*
After the controversies in October involving models "peeking at Git history" and "tampering with grading scripts" across major leaderboards, we know firsthand that environment cleanliness is a matter of life and death for training. During the packaging phase, every one of our engineering environments is sanitized by our proprietary static scanning tools: completely stripping away \origin/main\ remote residues and historical Commit spoilers, enforcing strict permission and filesystem isolation between the test executor (Verifier) and the model runtime container, and intercepting lingering process trees after timeouts as well as timing measurement blind spots. The environment delivered to foundation model labs is a clean examination room with all opportunistic backdoors thoroughly sealed.
\*Second, a three-tier grading system combining "execution verification + architectural Rubric + trajectory intent auditing."\*
Ordinary environments only provide binary 0 or 1 unit test results, where the signal is too sparse and easily gamed by models. We build three tiers of verification into our environments: the bottom tier consists of high-coverage functional and performance benchmark tests; the middle tier features code structure and maintainability Rubrics aligned with the aesthetics of core Maintainers; and the top tier introduces the latest trajectory intent verification mechanisms (similar to the Epistemic trajectory review and harmlessness checks proposed in early November), scanning in real time across hundreds of tool-call steps for covert behaviors such as deleting tests, altering configurations, or performing unauthorized operations—ensuring that every positive reward fed into GRPO/RL training reflects genuine engineering capability.
\*Third, an engineering team that understands both Agent Harnesses and post-training ablations.\*
Whether long-horizon coding data actually yields training gains depends half on the tasks themselves and half on the Agent Harness (the scaffolding and toolchain definitions wrapping the model). Rather than blindly delivering data like a traditional outsourcing vendor, our team deeply tracks the underlying mechanics of mainstream harnesses such as Claude Code, Codex, OpenCode, and Stirrup. Before delivery, we run multiple rounds of base model rollouts and difficulty stratification under standard harnesses to filter out invalid dead-end tasks caused by prompt ambiguity or hidden unfair constraints—ensuring that every batch of long-horizon engineering data delivered to model labs produces clear gains on both private test sets and real-world coding experience.
Ultimately, as the competition among coding agents shifts from "writing a runnable script" to "maintaining a million-line software engineering edifice," the barrier to entry in the data business has fundamentally changed.
Only a team that truly understands how large-scale software is written, reviewed, and executed inside containers can help large models cross the final hurdle from "leaderboard topper" to "qualified engineer."
About DataMining Founded by a team of PhD students from the Institute of Software at Peking University's School of Computer Science, we specialize in providing high-quality original task data and executable evaluation environments for LLM and agent R&D. We deliver not only data, but also industrial-grade Rubric and Harbor Task verification systems. ▸ Long-Horizon Code & Engineering Simulation: Deep SWE, Frontier SWE, Frontier-Eng, ALE / Terminal-Bench, etc., supporting stable delivery of 200 tasks/week within 7 business days. ▸ Extreme Math/Science & Professional Agents: HLE strict multimodal pipeline (5000+ tasks in stock); Harvey LAB, Automation Bench, Toolathlon, and 35+ atomic-level Rubrics industry workflow packages. ▸ System Infrastructure & Embodied Real-Robot Data: Standardized Win11 / Ubuntu desktop Agent VM images, as well as million-scale embodied AI Grounding / SFT / DAgger custom real-robot pipelines and cyber data. All research, datasets, and benchmarks cited in this article are public third-party works; we only align with their capability requirements and difficulty ranges without copying tasks. Capability descriptions herein represent our internal same-caliber conclusions and do not represent official third-party conclusions. 🌐 Website: datamining.cloud|📮 Sample Requests & Technical Inquiries: contact@datamining.cloud
📚 Image Sources
The 4 illustrations in this article are taken from public technical sources: the official Artificial Analysis leaderboard page, METR's report chart on SWE-bench patch merge rates, and screenshots of issue pages from the openai/codex repository on GitHub; captions only describe the visible content and do not represent official third-party conclusions.