What Does Terminal-Bench-Science Measure? A Science Agent Task Where Finding Every Region Matters
If you find a global optimum, does that mean you have the right answer?
Not necessarily. In scientific computing, the harder part may be proving that you found every region of optimal solutions. Miss even one narrow region, and the probabilities, covariances, and inferred parameters that follow may all shift.
That is what makes scientific-agent tasks interesting. They test more than whether a model can call Python or get a program to run. They ask whether it understands the mathematical structure, reports the result completely, and leaves enough evidence for someone else to check it.
01What is Terminal-Bench-Science designed to measure?
Terminal-Bench-Science (TB-Science) focuses on whether an agent can complete a scientific research workflow in a terminal. It is not simply a knowledge question followed by a final answer. Tasks can require an agent to understand a research problem, write and run code, process data or simulations, and produce results that can be inspected.
The workflow matters. A model may know the formula and still miss a boundary condition in its implementation. A program may run successfully while its output fails to answer the actual question. Evaluating this kind of ability calls for clear inputs, an executable environment, and verifiable outputs. The public project involves scientific-domain experts in task design and review, and it evolves over time; task counts therefore depend on the version. This article does not treat any one release's size as permanent.
DataMining has built a set of scientific-computing terminal tasks inspired by this capability area. They are our own examples, not official Terminal-Bench-Science tasks, leaderboard results, or a collaboration with the project. The scenario is integer phase calibration and parameter inversion: given control parameters and observation constraints, an agent must identify all globally optimal integer-solution regions, compute statistics from them, and infer the underlying parameters.
02Why is a denser grid not enough?
Here is an intuitive way to picture the problem. As continuous control parameters change, the integer solution can change when the parameters cross a boundary. The parameter space is therefore divided into many small regions, each associated with an integer solution. The task is not to test a few points or find one minimum. It is to enumerate every globally optimal region with positive volume.
When a solver samples only a finite grid, a narrow region may fall between sample points. The resulting plot can look smooth and plausible even though an entire region has been skipped. Later calculations may be precise, but they are statistics over an incomplete region list. Marginal probabilities, covariances, higher moments, and the final parameter inversion can all be affected.
That is why these tasks distinguish finding a solution from proving that the search is complete. The solver proposes regions; the verification evidence checks the finite search bounds, region coverage, numerical identities, and whether the parameters exist and are unique. An agent has to keep continuous parameter space, integer optimization, and statistical calculations consistent instead of focusing on one local result.
03How did we screen the tasks?
The demo did not begin with three polished prompts. Its selection record contains eight candidates. Four were solved in trials under the recorded model and setup. One more was withdrawn because its reference answer had missed a very small region. Three remained: a four-control coupled task, an eight-control chain task, and an eight-control ring task.
The withdrawn task is worth explaining. An independent region-overlay check found 358 positive-area regions, while the frozen reference answer listed 357. The omitted cell had an area of about 6.16×10⁻¹³; a probability cutoff in the reference solution had filtered it out. It is small enough to look like numerical noise, but the task asks for every region. We withdrew it before the difficulty evaluation and did not count the defect as a model failure.
This is why model scores cannot be the only check. If a model submits a different region count, it may look as if the model missed something, when the answer key may have missed it first. The reference has to be sound before the score means anything.
For the three retained tasks, the reference-solution records include region audits, independent numerical checks, comparisons against deliberately incorrect answers, and checks for parameter existence and uniqueness. The package also contains prompts, runtime environments, reference solutions, automated grading tests, selection records, and execution traces. Together, these let a reviewer follow what the task asks, what the program produces, and how the result is graded instead of relying on a final score alone.
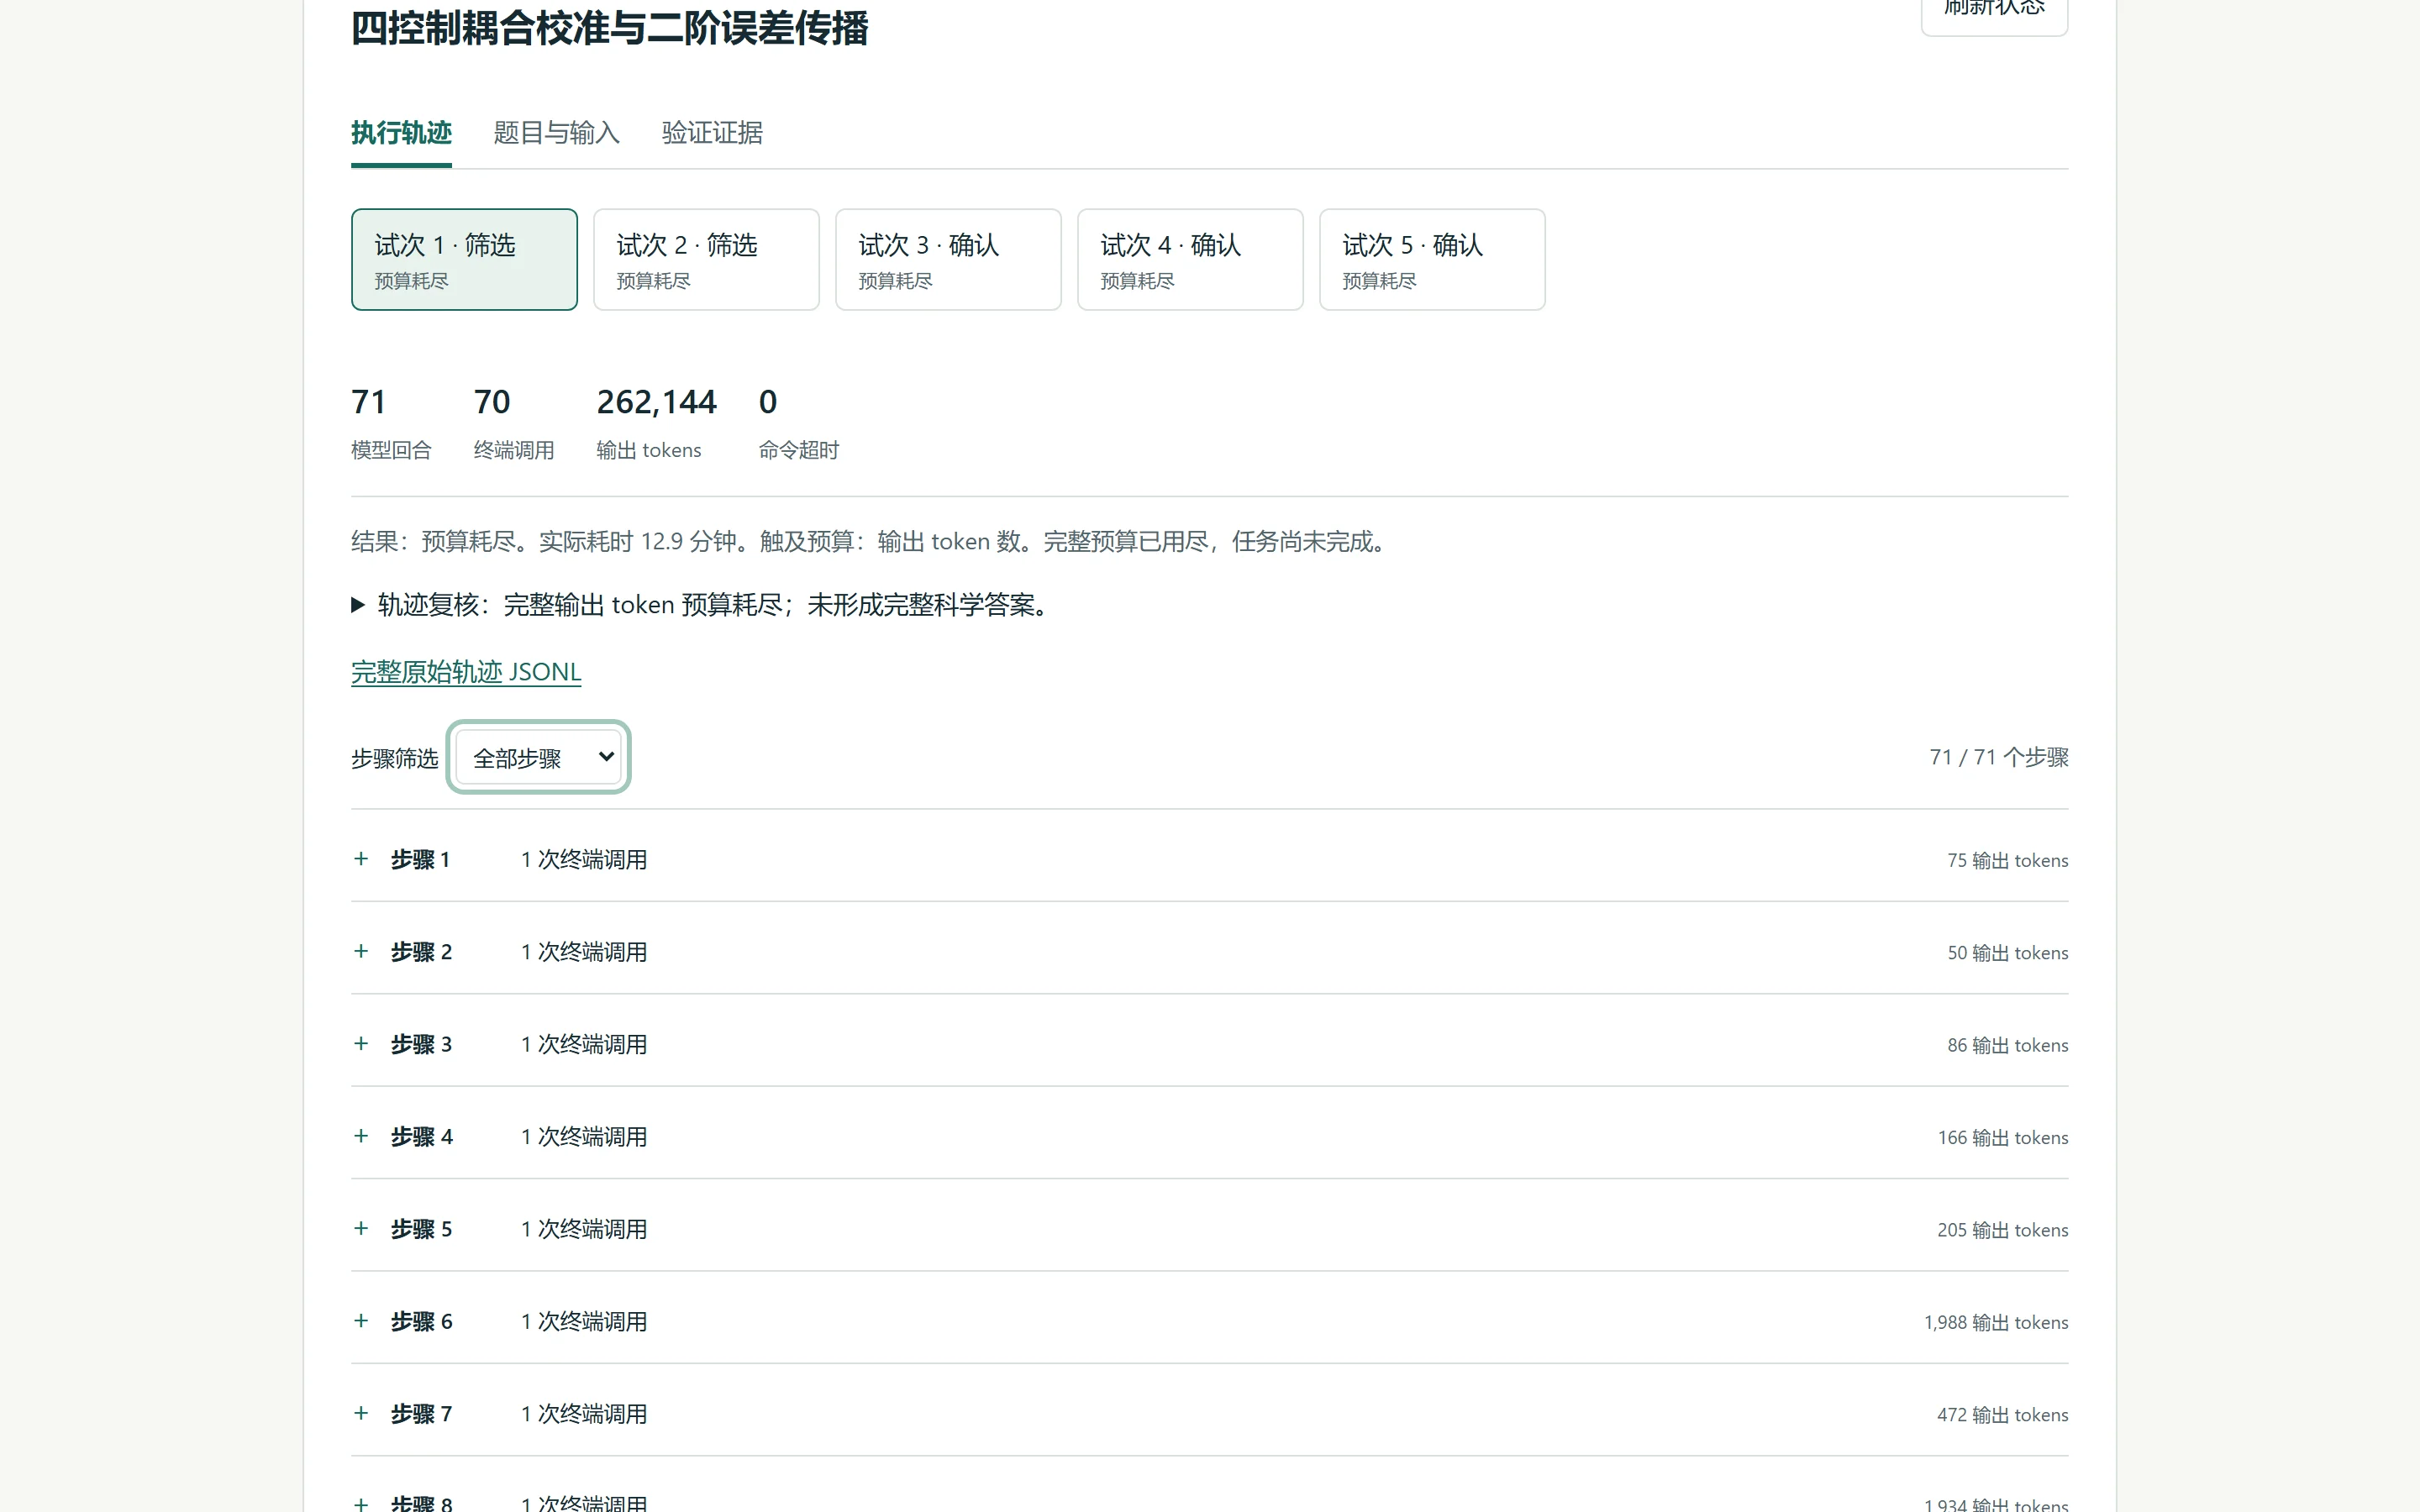
Caption: One run in the demo viewer. The interface exposes model responses, terminal commands, and their outputs step by step. The values shown belong to this trial and are not an overall model score.
04What can this kind of task help a team evaluate?
For teams building scientific or engineering agents, or evaluating long-horizon reasoning, difficulty alone is not enough. The practical questions are more specific: which capability does the task challenge? Was the reference answer checked independently? Can the grader detect a plausible-looking result that missed a region? Do the traces help locate whether a failure came from modeling, implementation, or numerical validation?
This demo grounds those questions in one concrete scientific-computing task. It does not establish model capability across all scientific fields or turn an internal evaluation into an industry ranking. It demonstrates a task-design approach: make complex computation executable, state key assumptions, and provide ways to inspect both answers and failures.
DataMining provides original task data for foundation-model and agent development across code, complex reasoning, multimodal, and agent tasks. The team was formed by PhD students from the Institute of Software at Peking University's School of Computer Science. Teams planning scientific-computing or long-horizon-agent training and evaluation data can discuss target capabilities, runtime requirements, and acceptance criteria with us.
05Alternative headlines
- What Does Terminal-Bench-Science Measure? Completing the Scientific Workflow Matters
- How Can One Tiny Missing Region Change the Answer to a Scientific-Computing Task?
- A Scientific Agent Must Do More Than Find an Answer. It Must Show It Has Not Missed One.
- From Eight Candidates to Three Tasks: How We Checked the Reference Answers
- Why Audit Every Region of Optimal Solutions?